
On-premise medical AI agents for reliable clinical decision-making
This study utilized deidentified, retrospective clinical data from the MIMIC-IV (version 2.2) and physician-curated cases from previously published reports in VivaBench. The collection of patient information and creation of the MIMIC-IV…
nature.com
Publisher
Sep 15, 2026 at 9:29 AM UTC · Updated 13 minutes ago · 18 min read
This study utilized deidentified, retrospective clinical data from the MIMIC-IV (version 2.2) and physician-curated cases from previously published reports in VivaBench. The collection of patient information and creation of the MIMIC-IV resource was reviewed and approved by the institutional review boards of the Beth Israel Deaconess Medical Center (BIDMC) and the Massachusetts Institute of Technology (MIT), which granted a waiver of informed consent. No participants were prospectively recruited or compensated for the present study, and no additional informed consent was obtained. All data processing was conducted within a fully on-premise, institutionally governed environment. No protected health information or deidentified clinical text was transmitted to, stored by or accessible to any external entities or model providers. All researchers involved in data analysis of this study completed the required CITI Program training (‘Data or Specimens Only Research’) and adhered strictly to the PhysioNet Credentialed Health Data Use Agreement.
Dataset
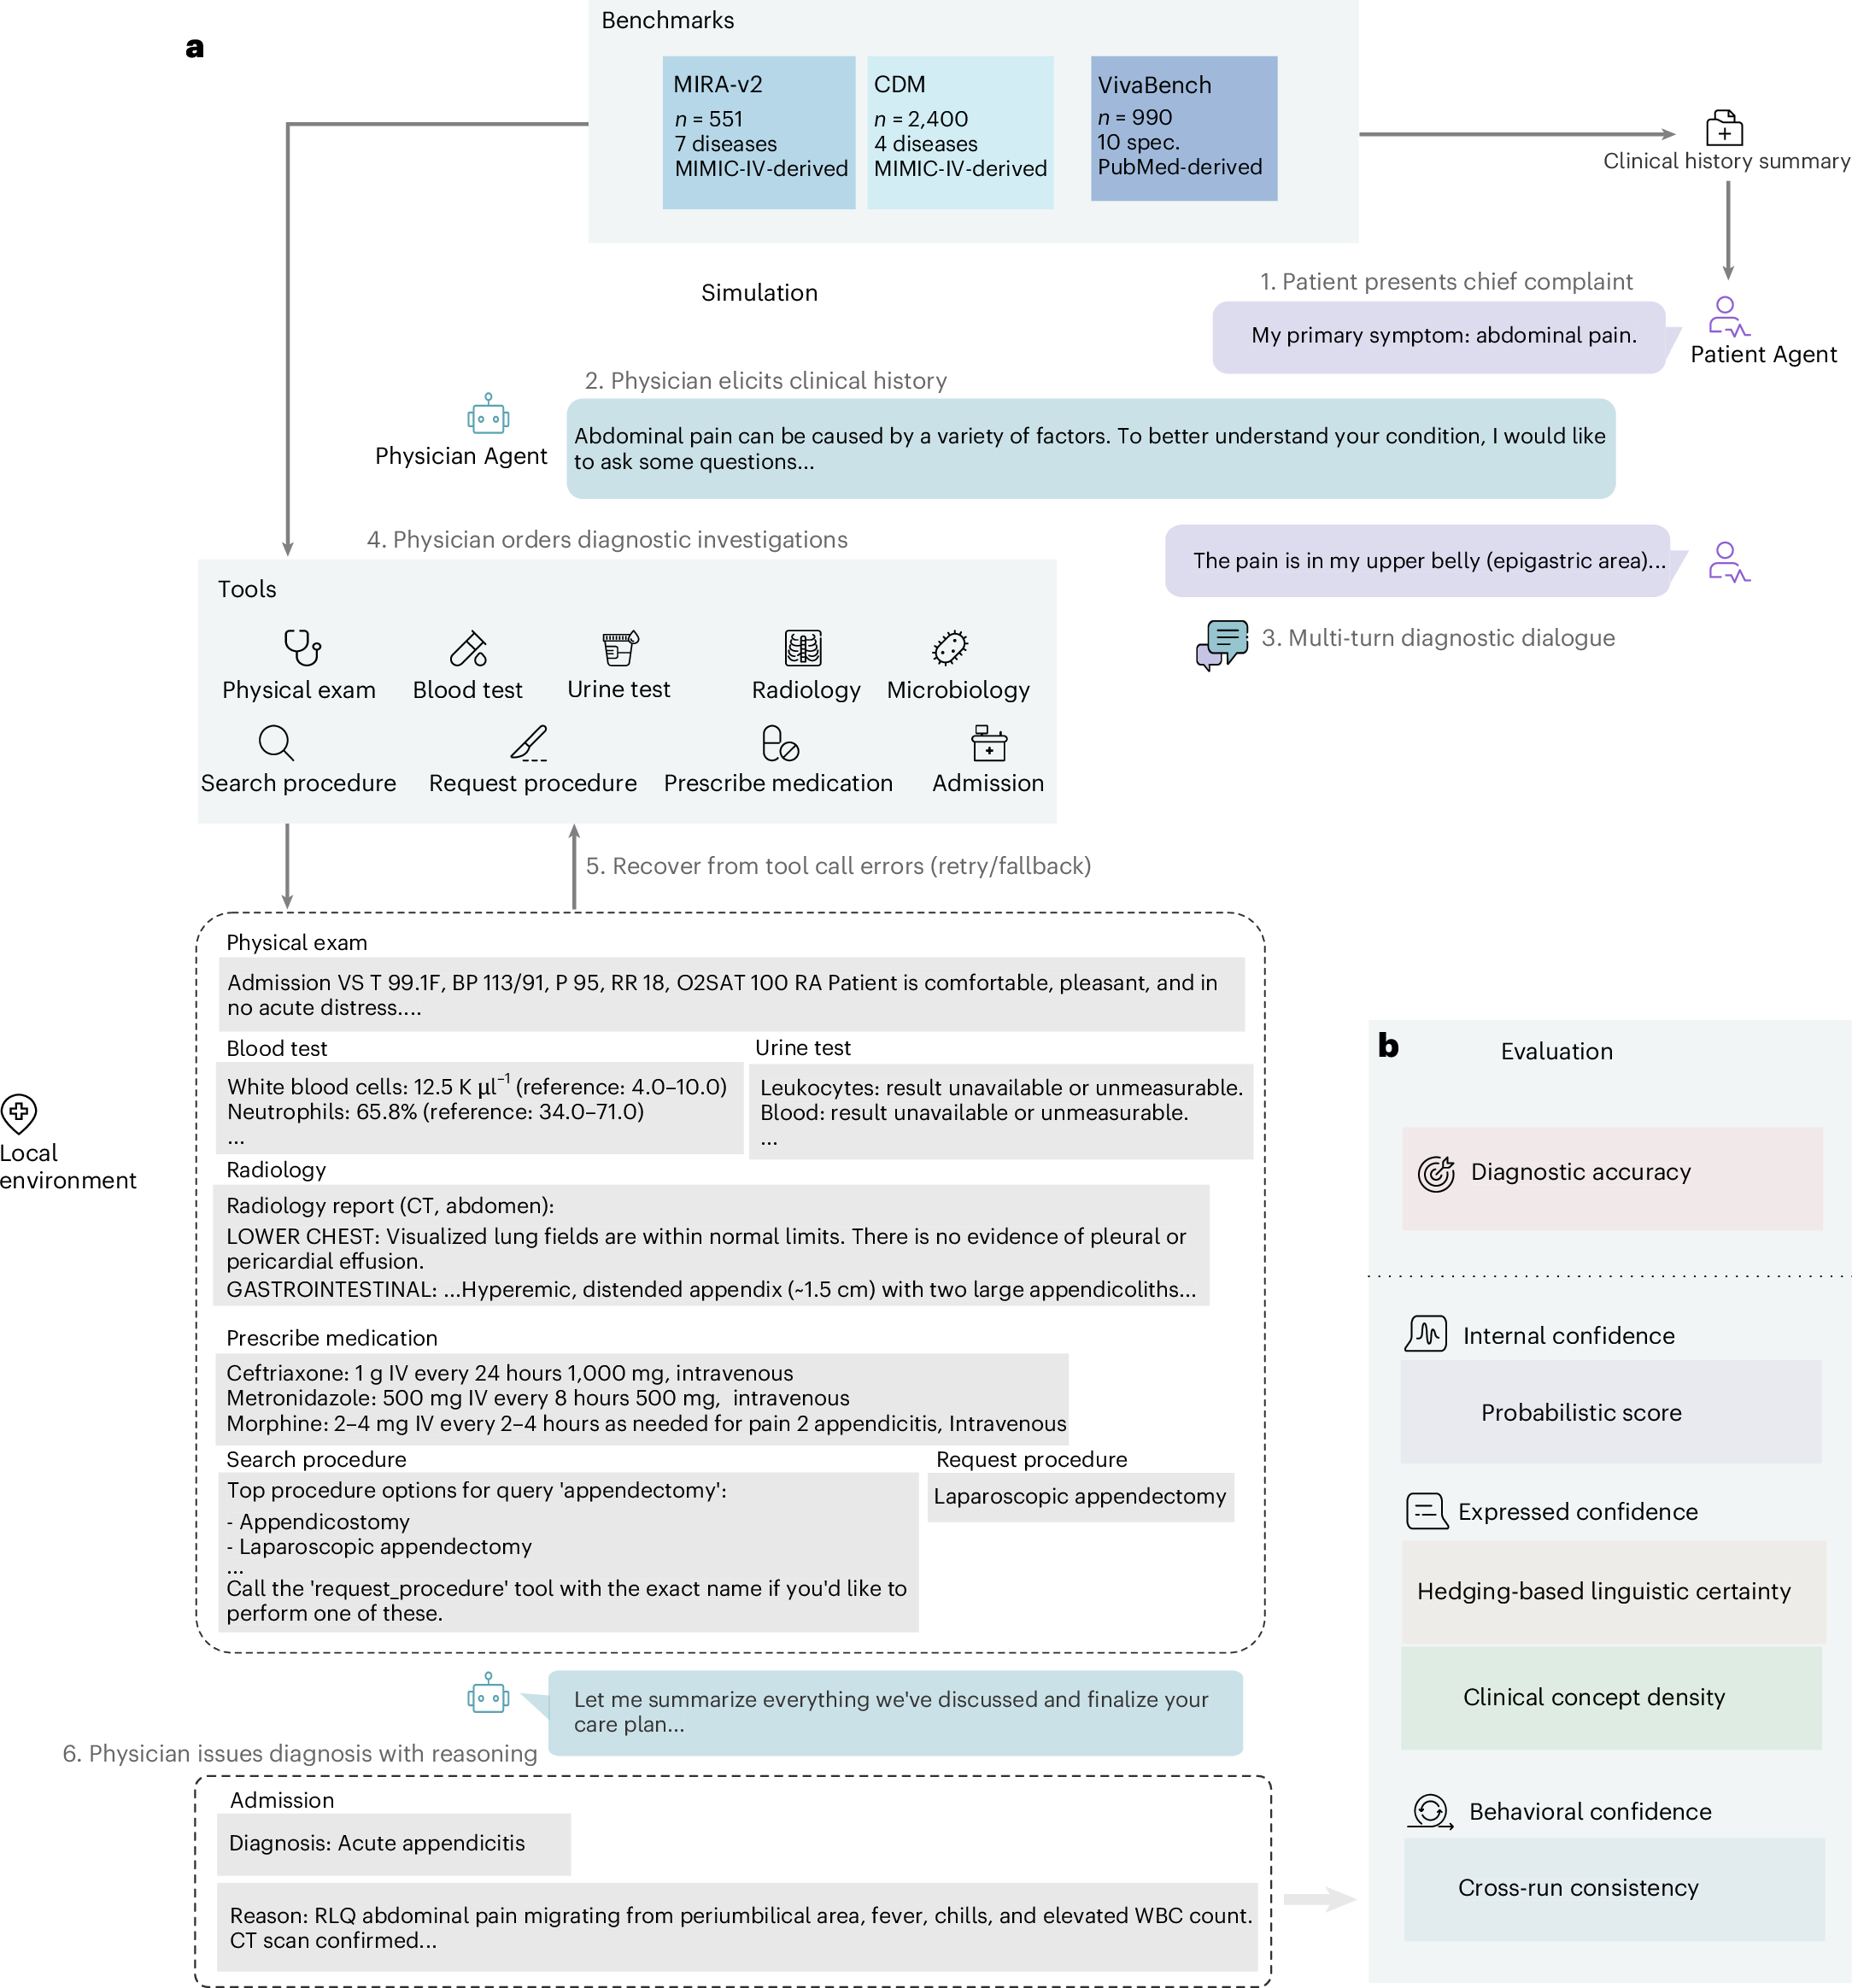
To evaluate the agent’s clinical reasoning capabilities across distinct diagnostic settings and to assess generalizability, we used three benchmarks spanning two independent data sources (Fig. 1). Two benchmarks are derived from MIMIC-IV, a publicly available dataset of deidentified EHRs from BIDMC: MIRA-v2 (n = 551; seven conditions), adapted from the MIRA29 framework, which serves as the primary benchmark for diagnostic decision-making, and CDM30 (n = 2,400; four acute abdominal conditions), which serves as a cross-validation benchmark for diagnostic reasoning at scale. A third benchmark, VivaBench32 (n = 990; 10 clinical specialty groups), provides independent external validation across a broad multi-specialty case mix. Each benchmark is described in detail in Extended Data Fig. 1a.
Article Intelligence
Topics
Sponsored
Ad
NewsLayerLearn more
NewsLayer Premium
Unlock deeper intelligence.
Ad-free reading, exclusive research, and real-time onchain insights.
Go Premium